Reading Notes
Overview / Deep Dive
Available src/paper-notes/hand-held-objects-reconstruction-3dv2026/coarse.md
Paper overview notes
Quickly assess the paper's scope, problem setting, core method, experimental findings, and whether to read it in depth.
Paper Reading Notes (Coarse): Reconstructing Hand-Held Objects in 3D from Images and Videos
1. Basic information
- Authors / affiliations: Jane Wu, Georgios Pavlakos, Georgia Gkioxari, Jitendra Malik; UC Berkeley, UT Austin, Caltech.
- Year / venue: 2026 / 3DV.
- Paper: OpenReview; arXiv PDF; Project.
- Reading mode: Overview.
2. Positioning in one sentence
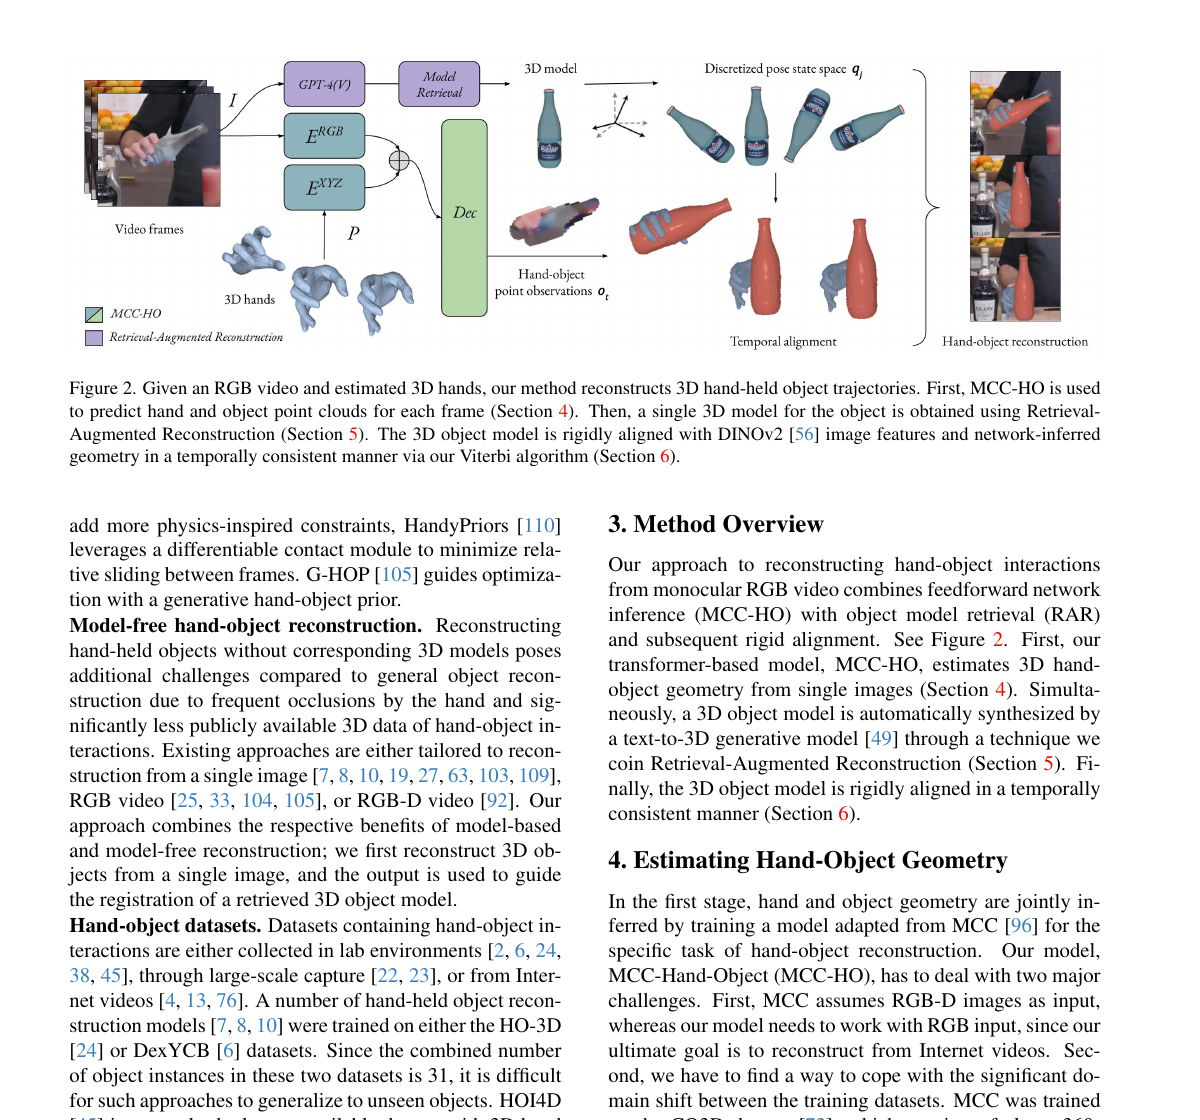
Using an inferred 3D hand as a scale / position anchor, MCC-HO reconstructs a handheld object from one image. Retrieval-Augmented Reconstruction (RAR) then retrieves a 3D asset and rigidly aligns it across frames.
3. Problem setting
- Input: one RGB image or RGB video and an estimated 3D hand; RAR additionally uses a VLM and text-to-3D / object assets.
- Output: hand-object geometry and, for video, a unified, temporally consistent object model with transforms.
- Challenges: hand occlusion, very few object pixels, and long-tail target shapes. This is not a fixed-CAD BOP pose estimator.
4. Method overview
- MCC-HO predicts hand-object geometry from RGB and a 3D hand.
- A VLM identifies / retrieves an observed-object-compatible 3D model; RAR rigidly aligns it with MCC-HO / image observations.
- The 3D hand reduces geometric ambiguity and enables object scale / location alignment across frames.
5. Experimental overview
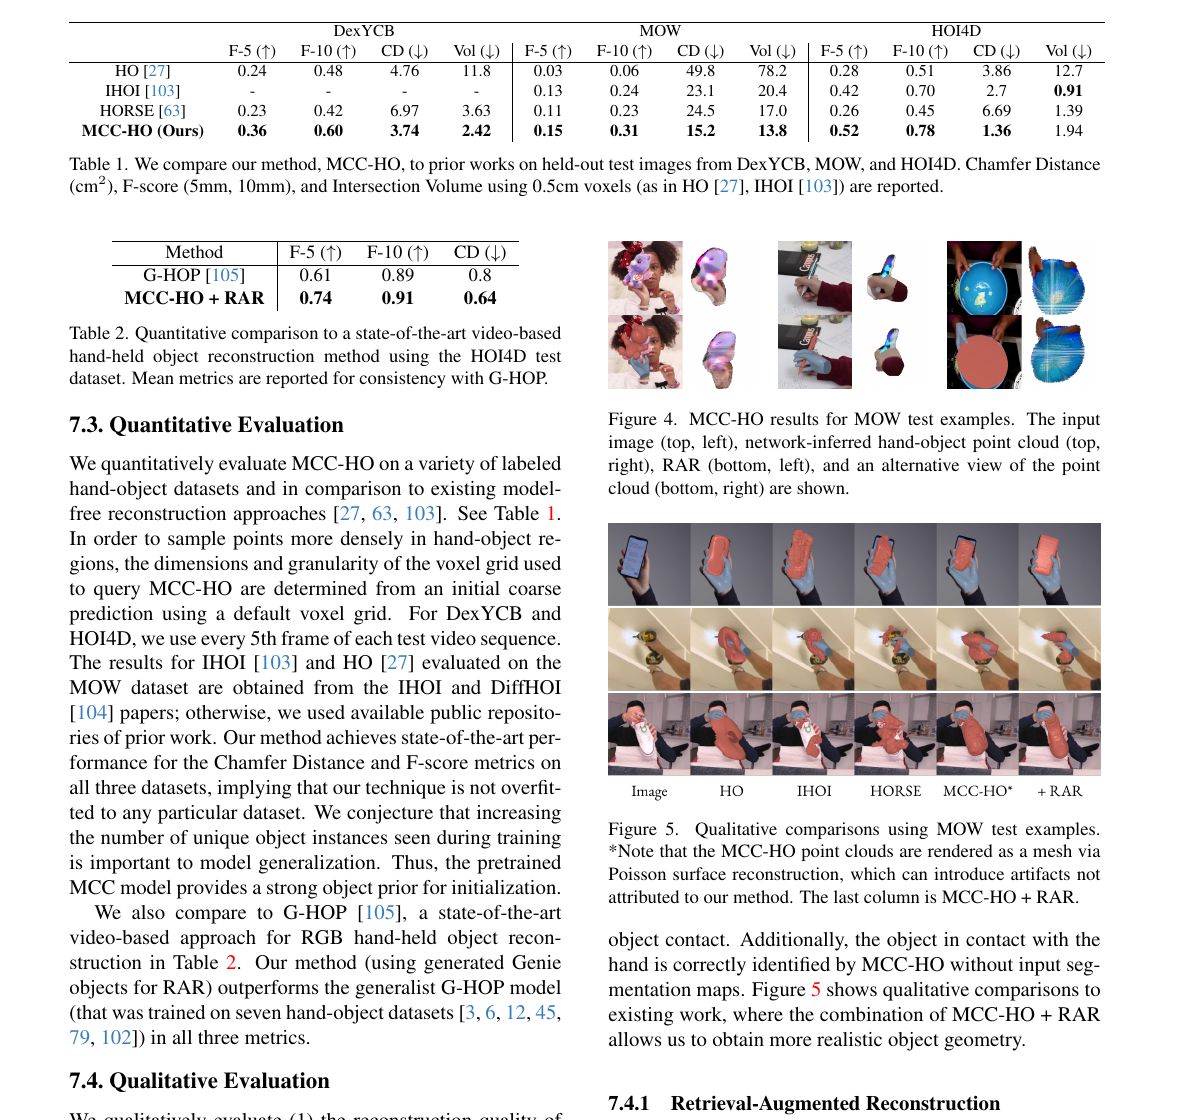
- Datasets: DexYCB, MOW, HOI4D; demonstrations also use unlabeled 100DOH.
- Single-frame MCC-HO on MOW: F5 / F10 / CD of 0.15 / 0.31 / 15.2, versus IHOI 0.13 / 0.24 / 23.1.
- HOI4D video: MCC-HO+RAR F5 / F10 / CD of 0.74 / 0.91 / 0.64, versus G-HOP 0.61 / 0.89 / 0.8.
6. Strengths, weaknesses, and implications
Strengths
- The hand strongly conditions object location / scale; RAR turns local single-image geometry into a reusable object asset.
Limitations / risks
- Depends on 3D hand estimation, VLM retrieval, and generated-asset quality; rigid alignment cannot repair retrieval of the wrong category.
- Joint reconstruction metrics measure pose only indirectly and cannot be directly compared with standard 6D pose AR.
7. Points for deeper reading
In the no-hand ablation, MOW CD rises from 15.2 to 71.6. This strongly supports explicit hand geometry as a potentially more important cue than a larger object prior in interaction scenes.