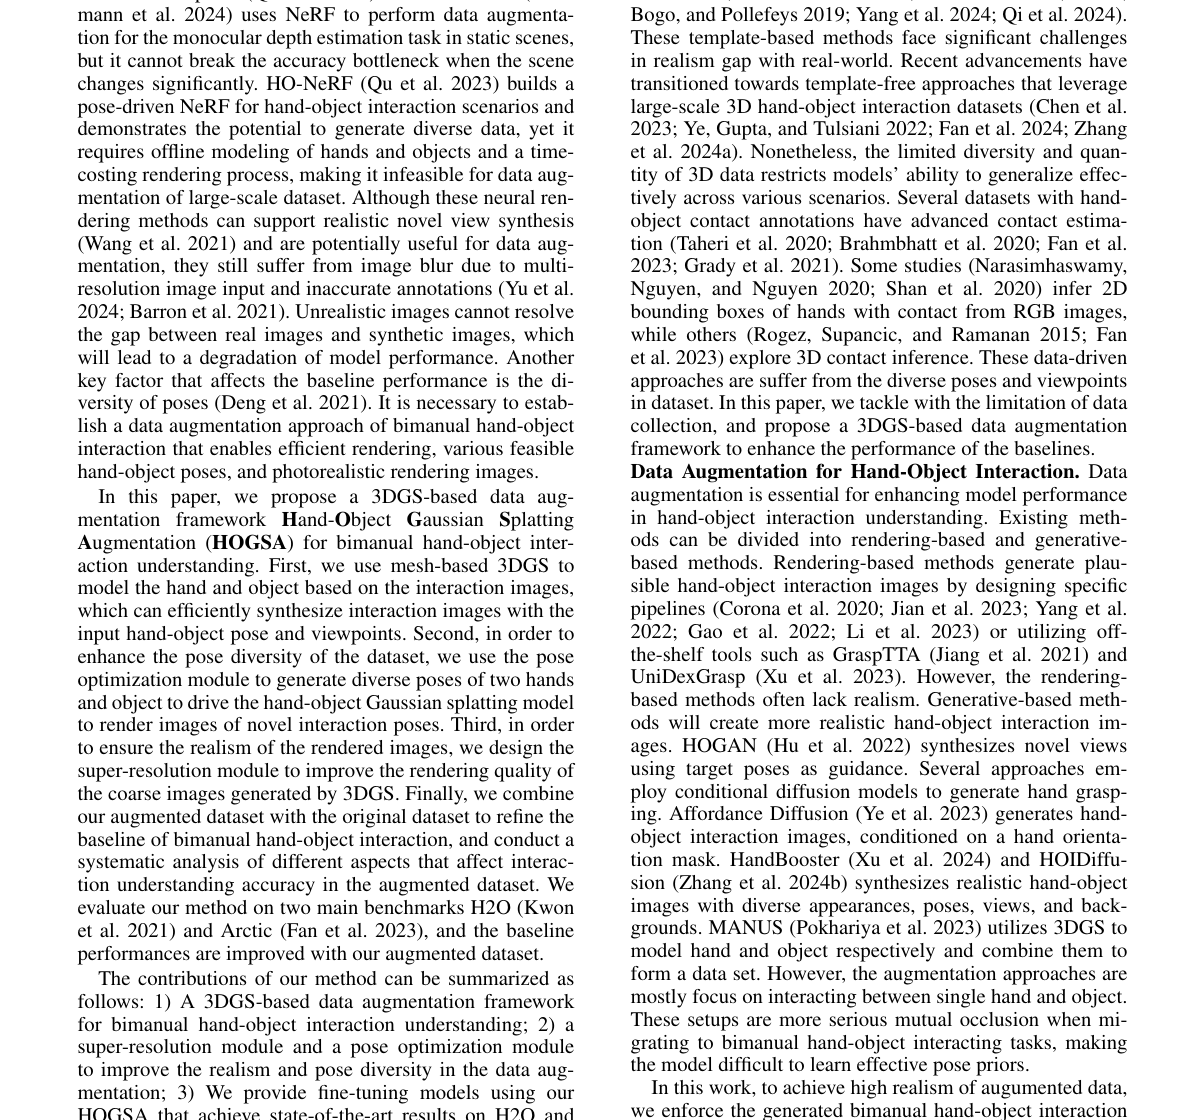
HOGSA: Bimanual Hand-Object Interaction Understanding with 3D Gaussian Splatting Based Data Augmentation
HOGSA creates high-quality bimanual hand–object training samples with mesh-based 3D Gaussian Splatting and super-resolution rendering. Optimizing bimanual grasp poses expands viewpoint and pose coverage to improve interaction-pose baselines.
hand-object capture sequencehand / object meshes or reconstruction supervision
Reading Notes
Overview / Deep Dive
Available src/paper-notes/hogsa/coarse.md
Paper overview notes
Quickly assess the paper's scope, problem setting, core method, experimental findings, and whether to read it in depth.
Overview: HOGSA
In one sentence
HOGSA is data augmentation for bimanual hand-object pose / interaction learning: mesh-based 3D Gaussian Splatting generates novel views and grasp poses, while super-resolution improves render usability.
Task boundaries
Input: captured hand-object interaction sequences and reconstruction / mesh supervision.
Output: augmented photorealistic hand-object images, rather than direct single-frame 6D pose predictions.
Value: fills interaction-training gaps in heavy occlusion, viewpoint diversity, and pose coverage.
Method overview
Mesh-based 3DGS constrains Gaussian points to reduce floating / missing geometry in unconstrained 3DGS.
The Super-Resolution Module restores high-frequency details such as textures and hand wrinkles.
Extend grasp-pose optimization to bimanual hand-object pose optimization, sampling more feasible interaction configurations.
Experimental evidence
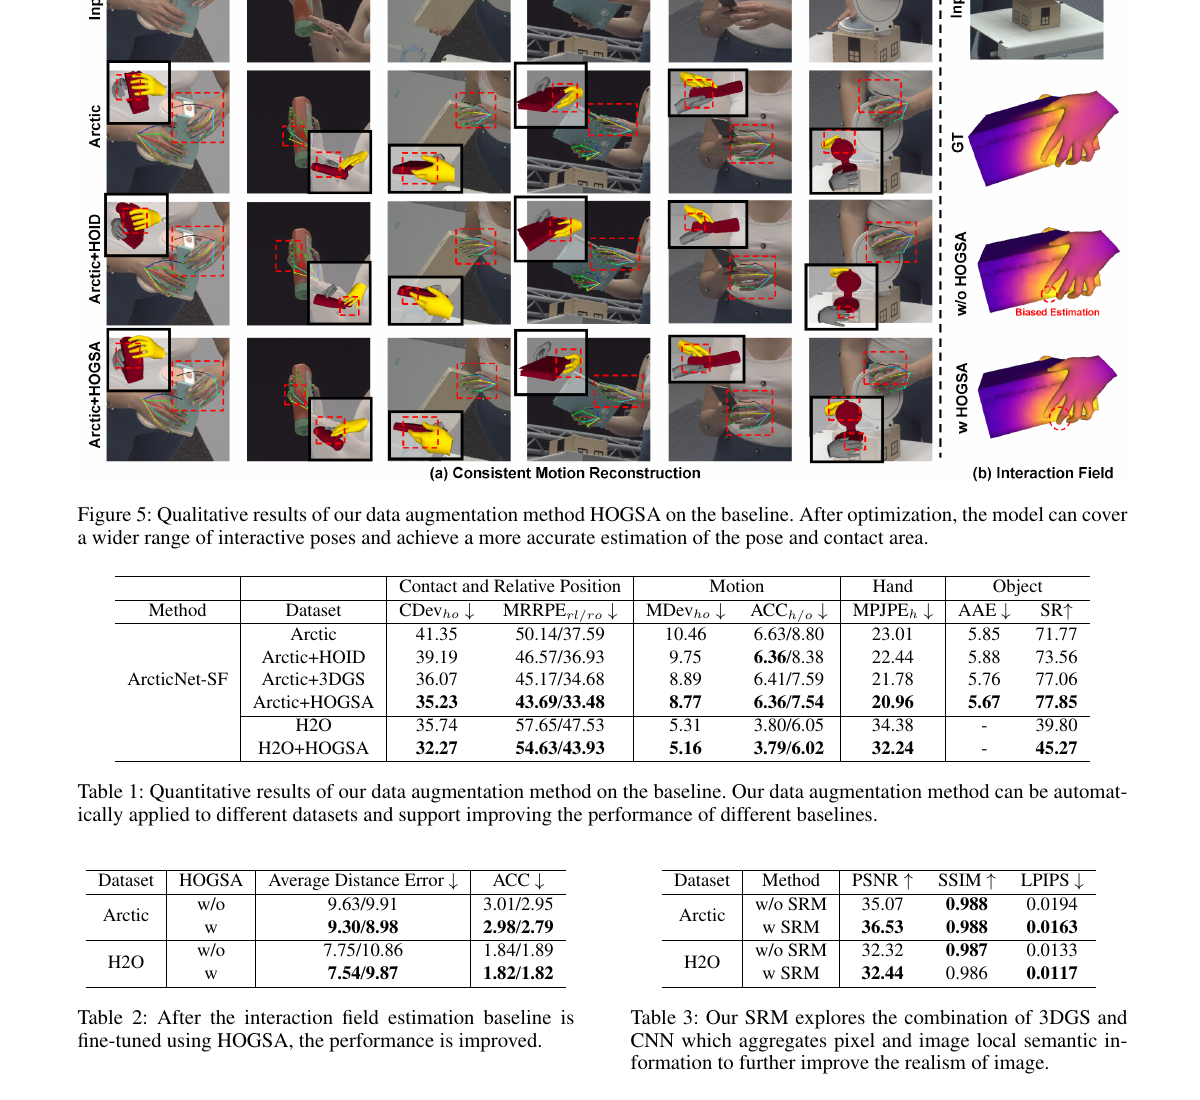
ARCTIC: ArcticNet-SF + HOGSA achieves MPJPE 20.96 versus original Arctic 23.01, and success rate 77.85 versus original 71.77.
HOGSA uses controllable, relatively high-fidelity 3DGS data generation to improve pose, viewpoint, and occlusion coverage in bimanual hand-object interactions, then tests gains for downstream interaction pose / motion baselines. It works on training data rather than directly predicting pose from one image.
2.1 Guide to the paper’s figures and tables
Figure / table
Reading focus
Method page
Distinguish the roles of mesh-based 3DGS, SRM, and bimanual pose optimization
Figure 5
Check coverage of gestures / views absent from the original training set, beyond image appearance
Tables 1–4
Downstream gains, rendering quality, and SRM / POM ablations together form the evidence chain
Excerpt from the original HOGSA method page. Source: official AAAI PDF. Image copyright belongs to the paper's authors and publisher; reproduced here for paper analysis.Excerpt from the original downstream data-augmentation results page. Source: official AAAI PDF. Image copyright belongs to the paper's authors and publisher; reproduced here for paper analysis.
3. Problem boundaries
Hands, objects, and contact regions occlude one another in bimanual manipulation; real annotated data rarely covers all grasps and relative motions evenly.
Standard 3DGS can produce floating points, local holes, and blurry rendering. Adding such synthetic images directly to training can widen the domain gap.
HOGSA takes hand-object capture / reconstruction sequences and required geometric constraints, producing augmented images and annotations for pose learning.
4. Method breakdown
Module
Function
Downstream significance
Mesh-based 3DGS
Constrain Gaussian splats using meshes
Reduce floating points and geometric distortion at hand-object boundaries
SRM
Super-resolution module combining 3DGS + CNN
Restore object textures, hand wrinkles, and other local details useful to downstream networks
Bimanual POM
Optimize grasp poses / views from bimanual joints
Expand feasible interaction configurations rather than duplicate frames
Rendered augmentation
Synthesize new RGB and corresponding annotations
Retrain baselines such as ArcticNet-SF and InterField-SF
The paper generates 82 HOGS models and about 1.7 million new images for ARCTIC (about +113%); 24 HOGS models and about 700K new images for H2O (about +175%). This is substantial data production, not a lightweight module trained once for deployment.
On ARCTIC, Full (SRM+POM) outperforms removing either module: Full CDev is 35.23, MPJPE 20.96, and SR 77.85. This supports improving both rendering fidelity and pose distribution together.
6. Critical analysis and implications
Strengths: ablates data diversity and rendering fidelity separately; reports downstream interaction, contact, hand, and object metrics; explicitly targets bimanual occlusion.
Limitations: requires capture / reconstruction / mesh conditions and substantial data-generation effort. Reported 0.06 s per image excludes initial HOGS reconstruction and the data pipeline. Generalization to new object categories, cameras, and large material changes remains unverified.
Implications: when pose systems lack data coverage, synthetic data should explicitly improve pose / contact distributions alongside photorealism. Report real and synthetic contributions separately before deployment to check that gains go beyond near-duplicate training examples.