Reading Notes
Overview / Deep Dive
Paper overview notes
Quickly assess the paper's scope, problem setting, core method, experimental findings, and whether to read it in depth.
Overview Notes: ZeroBP: Learning Position-Aware Correspondence for Zero-Shot 6D Pose Estimation in Bin-Picking
1. Basic information
- Authors: Jianqiu Chen, Zikun Zhou, Xin Li, Ye Zheng, Tianpeng Bao, Zhenyu He
- Venue: ICRA 2025
- Paper: arXiv:2502.01004
- PDF: Authors’ public full text
- Reading mode: Overview
2. Positioning in one sentence
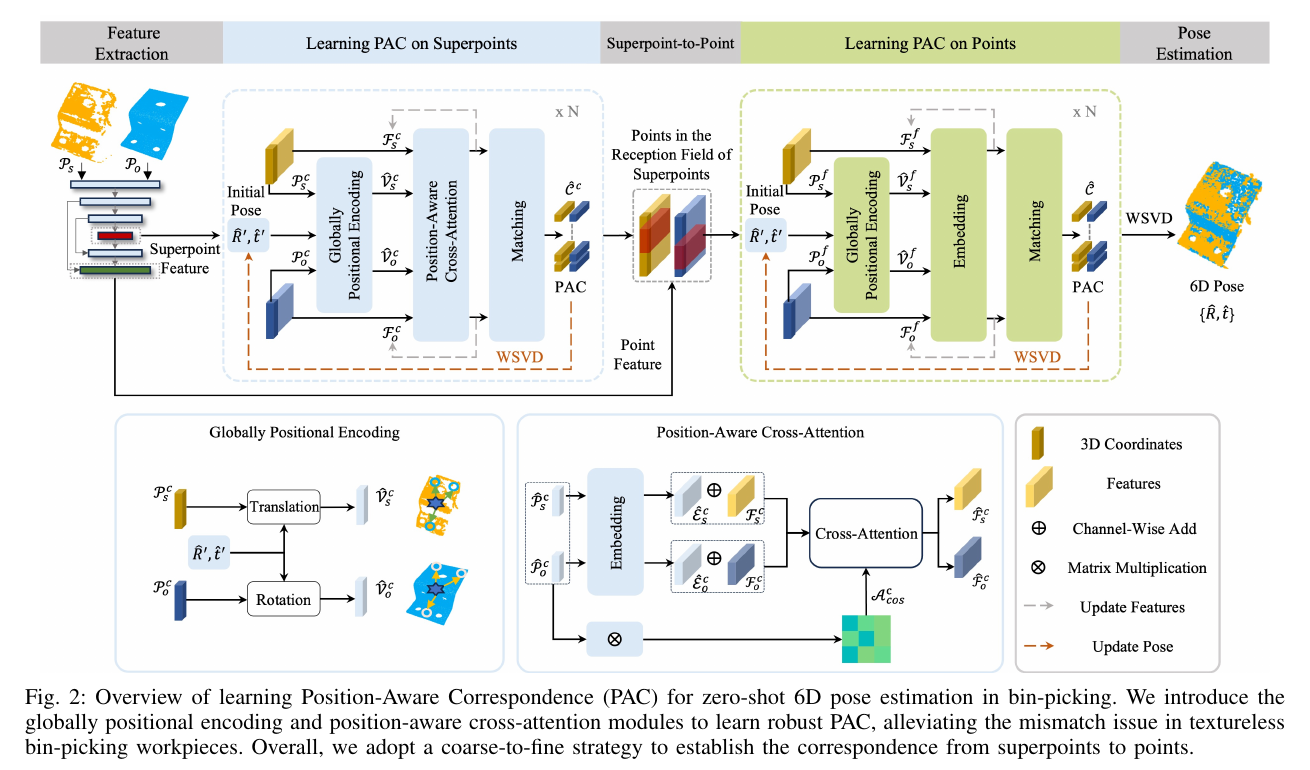
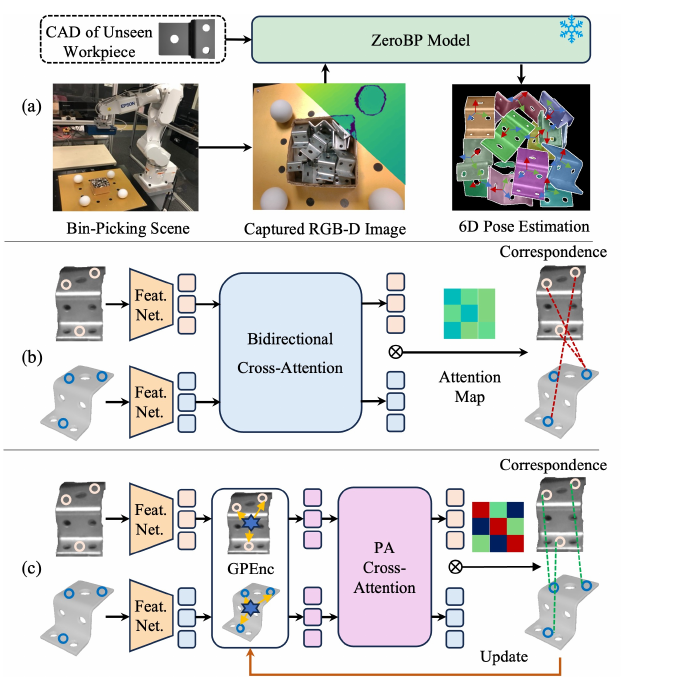
ZeroBP encodes directions between points and object centers into cross-attention, going beyond local appearance. At superpoint and point levels, it alternates correspondence, pose, and global-position updates to reduce mismatches caused by repeated industrial-part geometry.
2.1 Guide to the paper’s figures and tables
| Figure / table | Content | Reading focus |
|---|---|---|
| Figure 1 | ZeroBP versus existing zero-shot methods | Position-aware correspondence is the key distinction |
| Figure 2 | PAC and coarse-to-fine pipeline | Coarse superpoint matching precedes fine point matching with alternating updates |
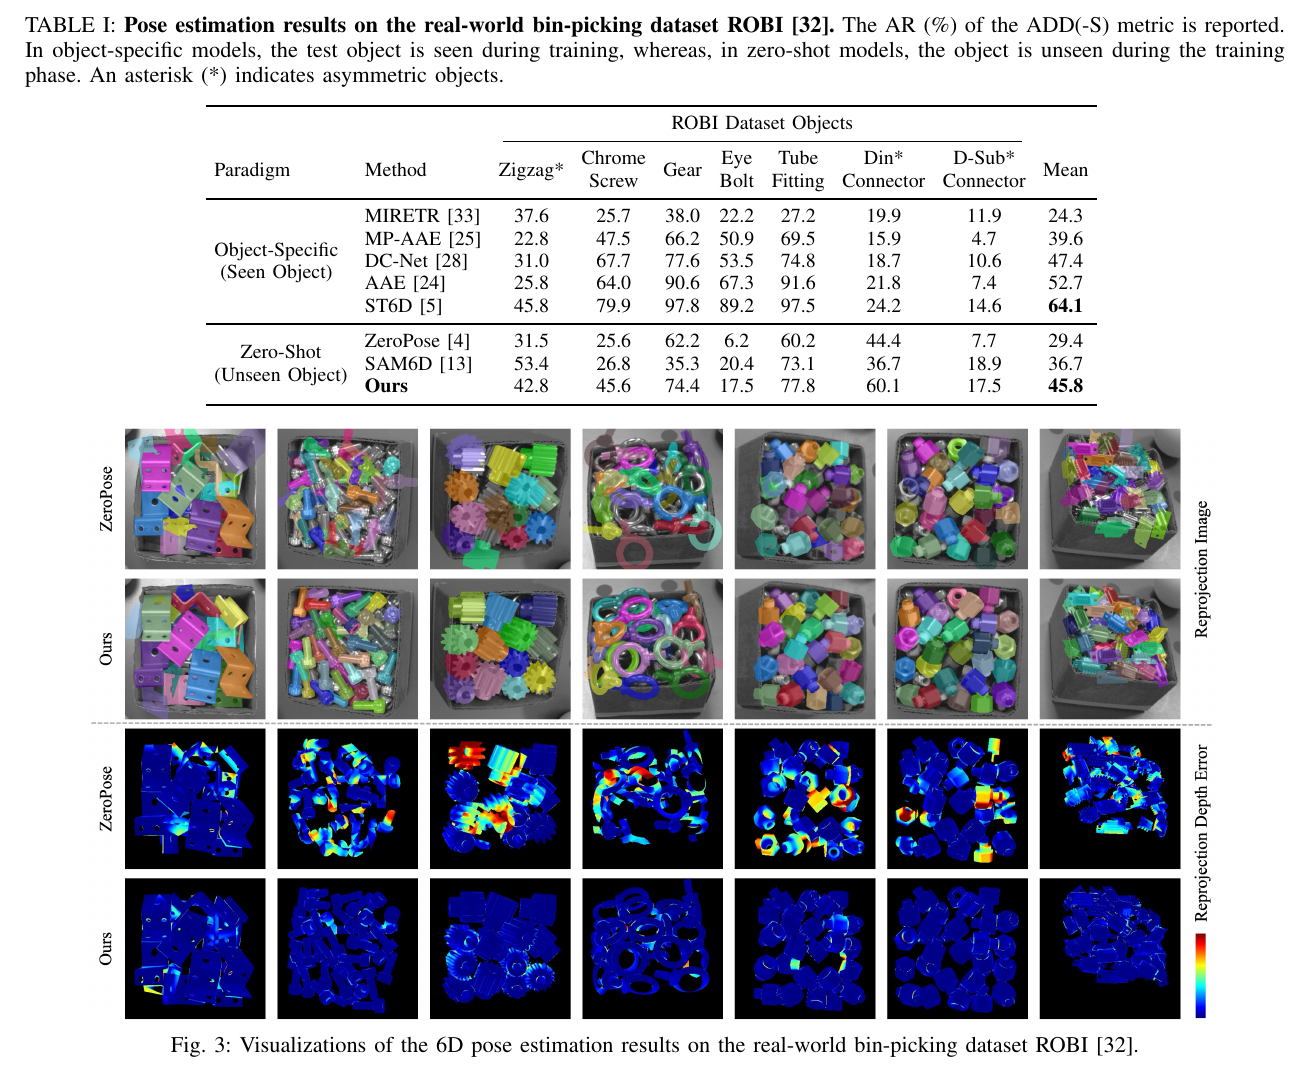
| Table I / Figure 3 | ROBI main results and qualitative alignment | The general model trails object-specific training but clearly exceeds zero-shot baselines |
3. Task setting
- Inputs: bin RGB-D, object CAD cloud, camera intrinsics, and picking-box region.
- Output: 6D poses of object instances unseen during training.
- Training: 1000 Google Scanned Objects and about 1 million synthetic RGB-D images.
- Testing: ROBI, with 7 reflective or weakly textured metal objects, 14 scenes, 1218 images, over 20K instances, and up to about 38 instances per bin.
4. Method pipeline
- Picking-box-aware detection / segmentation extracts candidate instances.
- KPConv-FPN encodes scene and CAD point clouds separately.
- Position-aware superpoint correspondence yields coarse matches.
- Current pose estimates object center and point-to-center directions.
- Multiplicative positional encoding injects directions into cross-attention.
- Point-level matching alternates with pose and global-position refinement.
- Weighted SVD solves the rigid transform.
5. Results at a glance
Mean ADD(-S) recall on ROBI:
| Method | Mean AR |
|---|---|
| ZeroPose | 29.4 |
| SAM-6D | 36.7 |
| ZeroBP | 45.8 |
| ST6D (object-specific) | 64.1 |
ZeroBP improves over the contemporary zero-shot baseline by 9.1 percentage points, while remaining well below ROBI-object-trained ST6D.
6. Coarse reading conclusion
Repeated holes, edges, and cylinders make local industrial geometry ambiguous; reliable correspondence needs its location within the whole object. ZeroBP suits frequently changing bin-picking objects with available CAD, provided depth, instance masks, and coarse-center estimates remain stable.