GeoReF: Geometric Alignment Across Shape Variation for Category-level Object Pose Refinement
GeoReF aligns observed instances and category shape priors with an HS-layer and three learned affine transforms. Cross-Cloud Transformation mixes both clouds' features and regresses rotation, translation, and size residuals. With SPD initialization, REAL275 reaches IoU75 51.8 and 5°2cm 54.4. Using only 2% of CAMERA25 training images still achieves IoU75 77.5.
observed RGB-D point cloudcategory shape-prior point cloudinitial rotation / translation / size
Requirements
initial category-level pose and size estimatevalid depth and object point cloudcategory shape prior512 observed and 512 prior pointsiterative refinement
Full paper metadataAuthors, affiliations, research area, datasets, metrics, method tags, and reading statusExpandCollapse
Authors
Linfang Zheng, Tze Ho Elden Tse, Chen Wang, Yinghan Sun, Hua Chen, Aleš Leonardis, Wei Zhang, Hyung Jin Chang
Affiliations
Southern University of Science and Technology / The University of Hong Kong / University of Birmingham
initial category-level pose and size estimatevalid depth and object point cloudcategory shape prior512 observed and 512 prior pointsiterative refinement
Reading Notes
Overview / Deep Dive
Available src/paper-notes/georef-cvpr2024/coarse.md
Paper overview notes
Quickly assess the paper's scope, problem setting, core method, experimental findings, and whether to read it in depth.
Paper Reading Notes (Coarse): GeoReF
1. Basic information
Title: GeoReF: Geometric Alignment Across Shape Variation for Category-level Object Pose Refinement
Authors: Linfang Zheng, Tze Ho Elden Tse, Chen Wang, Yinghan Sun, Hua Chen, Aleš Leonardis, Wei Zhang, Hyung Jin Chang
Affiliations: Southern University of Science and Technology; The University of Hong Kong; University of Birmingham
GeoReF refines category-level RGB-D pose from initial R,t,s, an observed cloud, and a category shape prior. Learnable affine and cross-cloud feature transforms adapt to within-category shape variation, iteratively regressing rotation, translation, and size residuals.
3. Guide to figures and tables
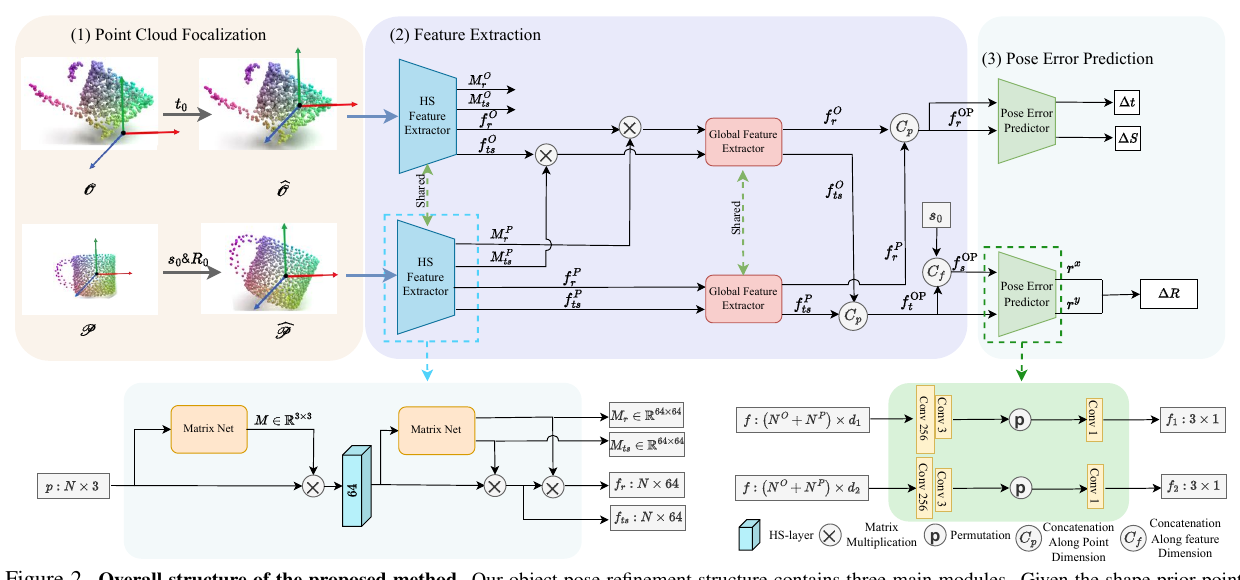
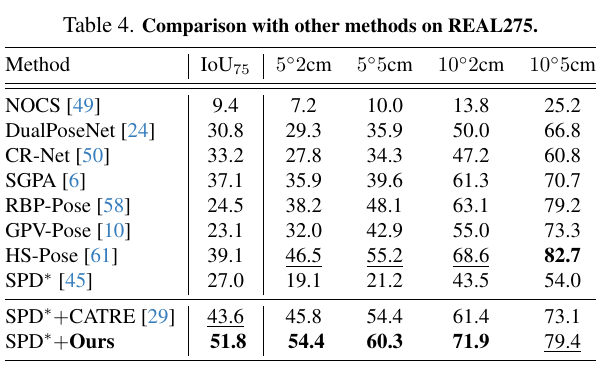
Method region of original Figure 2: initial pose focalizes both clouds; HS features and learnable affine transforms align geometry; Cross-Cloud Transformation exchanges information; separate heads predict rotation and translation / size errors. Source: official CVPR 2024 paper. Image copyright belongs to the paper's authors and IEEE/CVF; reproduced here for paper analysis.Original Table 4: SPD starts at IoU75 / 5°2cm 27.0 / 19.1, CATRE refinement gives 43.6 / 45.8, and GeoReF reaches 51.8 / 54.4. Source: official CVPR 2024 paper. Table copyright belongs to the paper's authors and IEEE/CVF; reproduced here for paper analysis.
4. Problem setting
Inputs: initial rotation, translation, and size (R0,t0,s0), observed cloud O, and category-prior cloud P.
Outputs: residuals (ΔR,Δt,Δs), usable over repeated refinement iterations.
Data: NOCS-REAL275 and NOCS-CAMERA25, with bottle, bowl, camera, can, laptop, and mug categories.
Support reproduction, comparison, related-work writing, and identifying opportunities for further research.
Paper Reading Notes (Deep): GeoReF
1. Key assessment
GeoReF starts from a CATRE failure: category-level refinement lacks the exact target CAD available to instance-level ICP. An observed narrow-mouth cup may differ from a wide-mouth mean prior. Separate PointNet encoding followed by late concatenation struggles to align shapes and can mistake prior mismatch for pose error.
The solution has three levels:
HS layers extract multiscale geometry;
Learnable Affine Transformations (LAT) adapt point and feature coordinates;
Cross-Cloud Transformation (CCT) explicitly applies prior-generated transforms to observed features.
REAL275 IoU75 improves from CATRE 43.6 to 51.8. More directly supporting shape adaptation are stable results under random prior replacement and outperforming full-data CATRE with only 2% of CAMERA25 training images.
2. Task Definition
Given:
(R0,t0,s0),O∈RNO×3,P∈RNP×3,
The network predicts:
(ΔR,Δt,Δs)=ϕ(R0,t0,s0,O,P).
Updated estimates can reenter the network iteratively. Each observed / prior cloud has 512 sampled points. This is category-level 9DoF: 3 rotation, 3 translation, and 3 metric-size dimensions, beyond 6DoF refinement alone.
It does not:
Detect objects from RGB;
Segment object clouds from depth;
Produce initial poses;
Learn category priors.
Upstream category estimators and preprocessing supply those inputs.
Subtract initial translation from observations and transform priors by initial rotation / anisotropic size into comparable coordinates. Remaining differences combine:
Initial pose / size errors;
Actual within-category shape variation;
Missing depth, occlusion, and noise.
Refinement must distinguish the first two: correct pose errors without turning shape variation into incorrect pose corrections.
4. HS Layers and Learnable Affine Transformations
Main structure of original Figure 2. The lower Matrix Net predicts three LAT groups for points and feature types; shared HS extraction feeds rotation and translation / size heads above. Source: official CVPR 2024 paper. Image copyright belongs to the paper's authors and IEEE/CVF; reproduced here for paper analysis.
Simply replacing PointNet with stronger geometry encoders hurts: HS-Encoder IoU75 is 30.1 and 3DGCN 28.4 versus CATRE PointNet 43.6. Strong single-cloud geometry operators do not automatically align different shapes.
Matrix Net produces:
M∈R3×3: adapts input points;
Mr∈R64×64: adapts rotation features;
Mts∈R64×64: adapts translation / size features.
These are learned affine alignments, not explicit rigid transforms. Rotation needs directional structure, while translation / size rely more on scale and centers, motivating separate transformations.
The ablations are clear:
Configuration
IoU75
5°2cm
5°5cm
Full GeoReF
51.8
54.4
60.3
No input-point LAT
39.3
46.6
53.0
No feature LAT
48.8
47.4
53.0
No separate rotation LAT
50.6
50.4
56.2
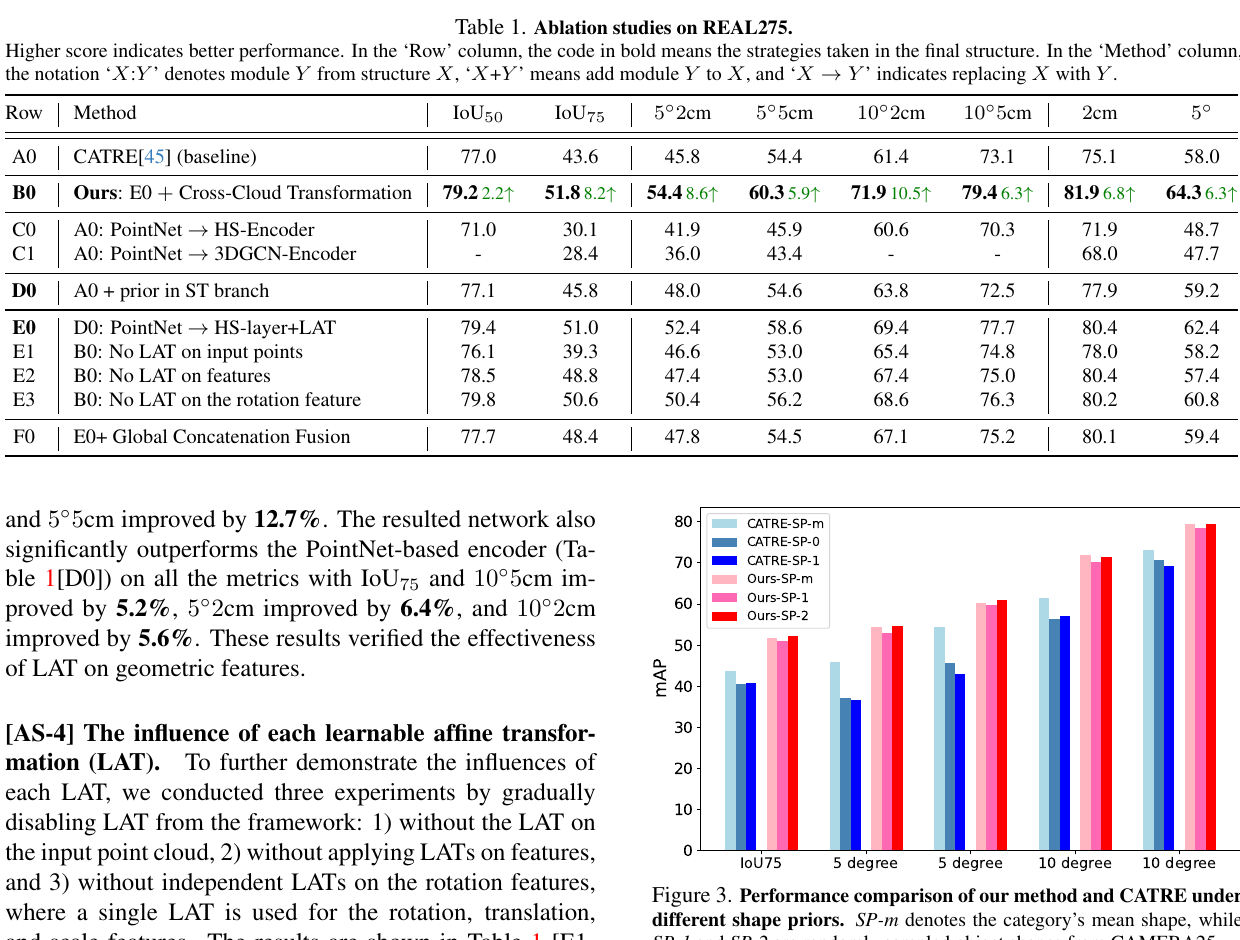
Input LAT matters most, highlighting coordinate compatibility before graph convolution.
5. Cross-Cloud Transformation
CATRE concatenates cloud features late. GeoReF applies prior-branch matrices to observations:
frO=MrPfrO,ftsO=MtsPftsO.
This is prior-conditioned feature-space alignment, not pointwise nearest-neighbor correspondence. Global aggregation combines both clouds before separate pose-error heads.
Global concatenation gives IoU75 / 5°2cm 48.4 / 47.8, versus CCT 51.8 / 54.4. Letting the other cloud change the feature basis works better than feeding adjacent vectors to an MLP.
The rotation head predicts 3D vectors rx,ry, with third axis:
rz=rx×ry.
Normalization / orthogonalization are still needed: cross product alone does not ensure R∈SO(3). Translation / size heads output Δt,Δs.
6. REAL275 Component Ablations
Original Table 1 and Figure 3: LAT, CCT, and prior-feature effects above; mean versus random shape priors below-right. CATRE is more sensitive to prior replacement while GeoReF remains steadier. Source: official CVPR 2024 paper. Figure and table copyright belongs to the paper's authors and IEEE/CVF; reproduced here for paper analysis.
The key progression in the full table:
Design
IoU75
5°2cm
10°2cm
CATRE
43.6
45.8
61.4
+ Prior in translation / size branch
45.8
48.0
63.8
+ HS-layer + LAT
51.0
52.4
69.4
+ CCT (full)
51.8
54.4
71.9
Priors help translation / size; LAT provides the largest gain; CCT completes cross-cloud fusion. Naive HS-Encoder replacement fails, so LAT enables geometry encoding for refinement rather than serving as an optional peripheral module.
7. Robustness across Initializations
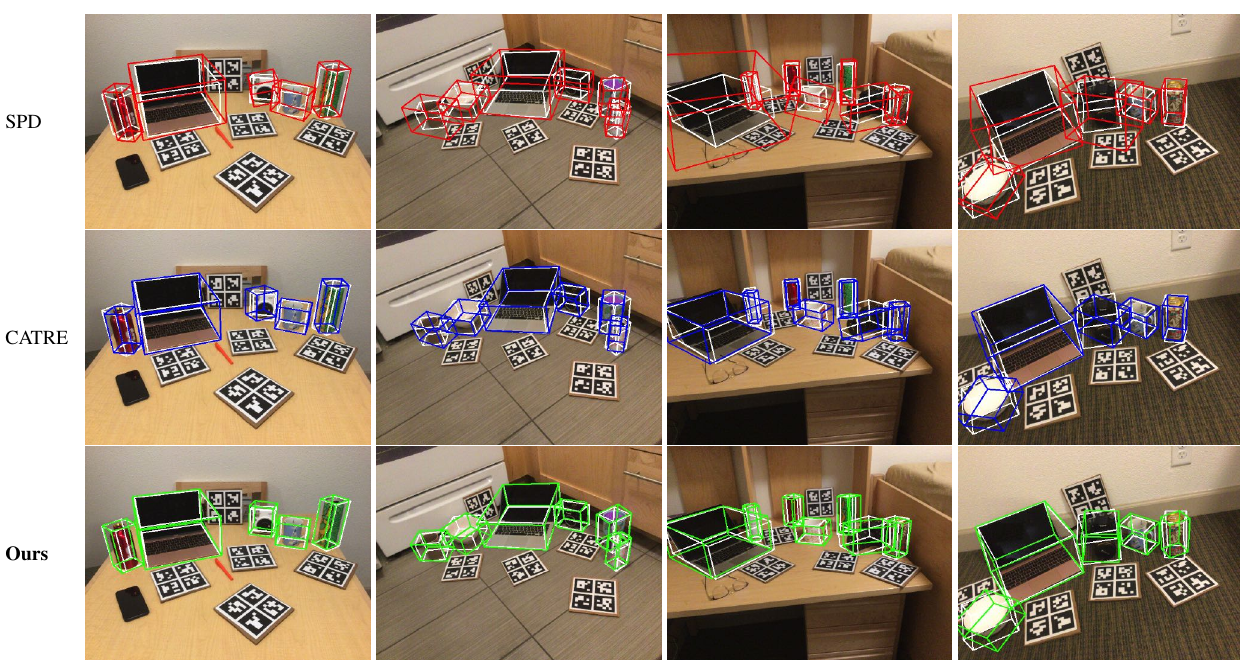
Original Figure 4: SPD, CATRE refinement, and GeoReF occupy successive rows. White lines are GT, colored lines estimates. GeoReF better matches box extents / orientation with shape-prior mismatch and mutual occlusion. Source: official CVPR 2024 paper. Image copyright belongs to the paper's authors and IEEE/CVF; reproduced here for paper analysis.
CATRE can reduce 10°2cm / 10°5cm from strong initial estimates; GeoReF improves all three initializations, suggesting less confusion of instance shape with pose residuals.
8. Generalization with Less Data
CAMERA25 has 275k training images. The paper samples only:
Method
Training images
IoU75
5°2cm
5°5cm
CATRE
275k
76.1
75.4
80.3
CATRE
5k
63.2
66.4
72.3
GeoReF
5k
77.5
75.4
81.1
CATRE
10k
66.5
69.7
75.5
GeoReF
10k
79.2
77.9
84.0
GeoReF with 5k beats CATRE with 275k on IoU75, supporting lower sample requirements from structure. It does not establish cross-category generalization: train / test still share six categories, varying instance / image counts.
9. Main Results and Correct Interpretation
Original Table 4: all GeoReF scores start from SPD estimates. Refined results are not directly comparable to single-stage estimators under identical compute assumptions. Source: official CVPR 2024 paper. Table copyright belongs to the paper's authors and IEEE/CVF; reproduced here for paper analysis.
Method
IoU75
5°2cm
5°5cm
10°2cm
10°5cm
SPD
27.0
19.1
21.2
43.5
54.0
SPD + CATRE
43.6
45.8
54.4
61.4
73.1
SPD + GeoReF
51.8
54.4
60.3
71.9
79.4
The authors distinguish estimators and refiners. GeoReF sees initial pose, a prior, and depth points over a longer pipeline. The table shows improvements to existing estimators, not fewer inputs to one model.
10. Training and Reproduction
GPU: RTX 4090;
batch 12, 150 epochs;
512 points per observed / prior cloud;
Ranger optimizer, base learning rate 10−4;
Cosine annealing starts at 72% of total epochs;
Augmentation: point dropout, Gaussian noise, pose perturbation;
Losses and base augmentations follow CATRE;
REAL275 ablations use SPD initial poses.
Conventions to verify:
A small CATRE IoU implementation issue is corrected under later protocols;
Compare refiners with the same initial estimator and iteration count;
Random priors come from CAMERA25 training, not unknown categories;
REAL275 has six categories and 36 objects, not representative open-category coverage.
11. Limitations
RGB-D and reliable masks are required; not RGB-only.
Category shape priors are required; articulated / nonrigid objects are unsupported.
Initial pose must lie within the convergence basin; badly focalized clouds may lack usable correspondences.
General affine feature transforms need not be physically interpretable or rigidly consistent.
Total detector / initializer / refiner latency is not a central reported metric.
Training / evaluation cover only six NOCS categories.
12. Overall assessment
GeoReF clarifies the central conflict: observation–prior mismatch combines pose error and shape variation; a stronger single-cloud encoder plus late concatenation cannot automatically separate them. LAT and CCT offer simple, well-supported cross-shape feature alignment.
It is a research baseline behind RGB-D category-level estimators, not a complete system. Deployment must evaluate segmentation, initialization, depth, iterations, and total latency together, beyond refined leaderboard scores.