MV-ROPE: Multi-View Constraints for Robust Category-Level Object Pose and Size Estimation
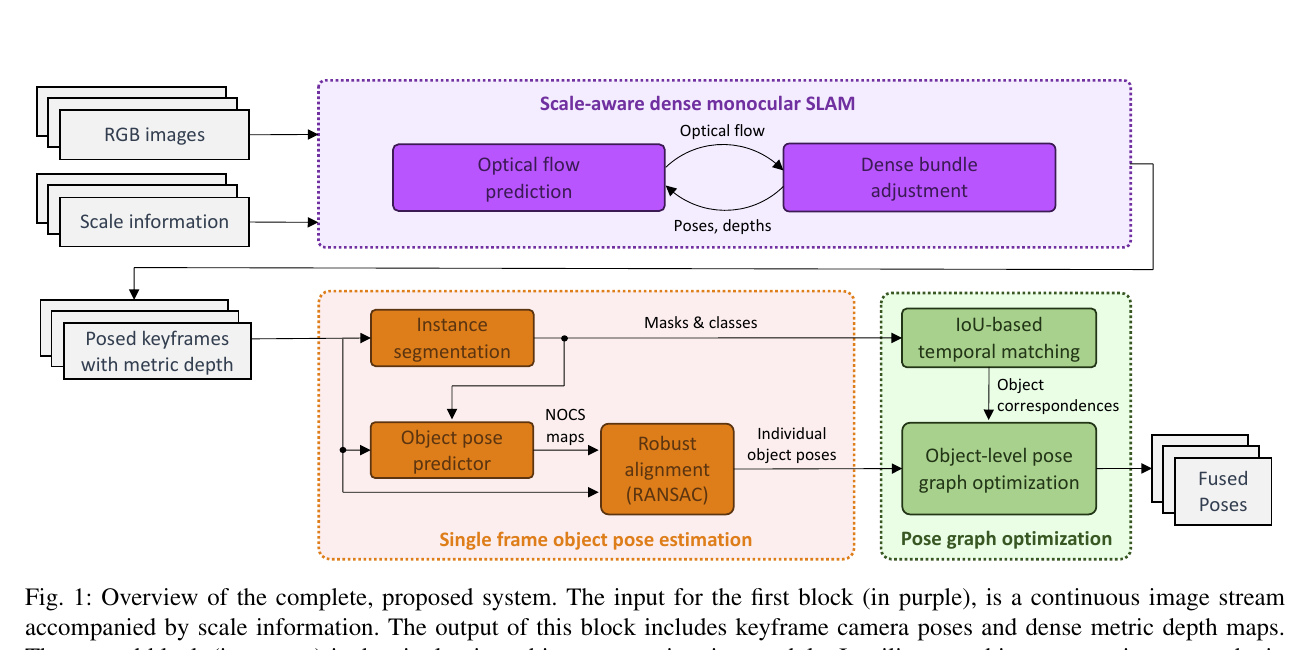
MV-ROPE recovers camera motion and metric depth from video with scale-aware dense monocular SLAM. NOCS–depth registration estimates keyframe object poses, while IoU association and an object-level pose graph fuse multiview constraints.
MV-ROPE replaces unstable single-frame depth with continuous RGB video and limited scale information. Scale-aware dense monocular SLAM comes first; keyframe NOCS predictions register to dense metric depth; cross-frame object identities, camera poses, and object poses then enter pose-graph optimization.
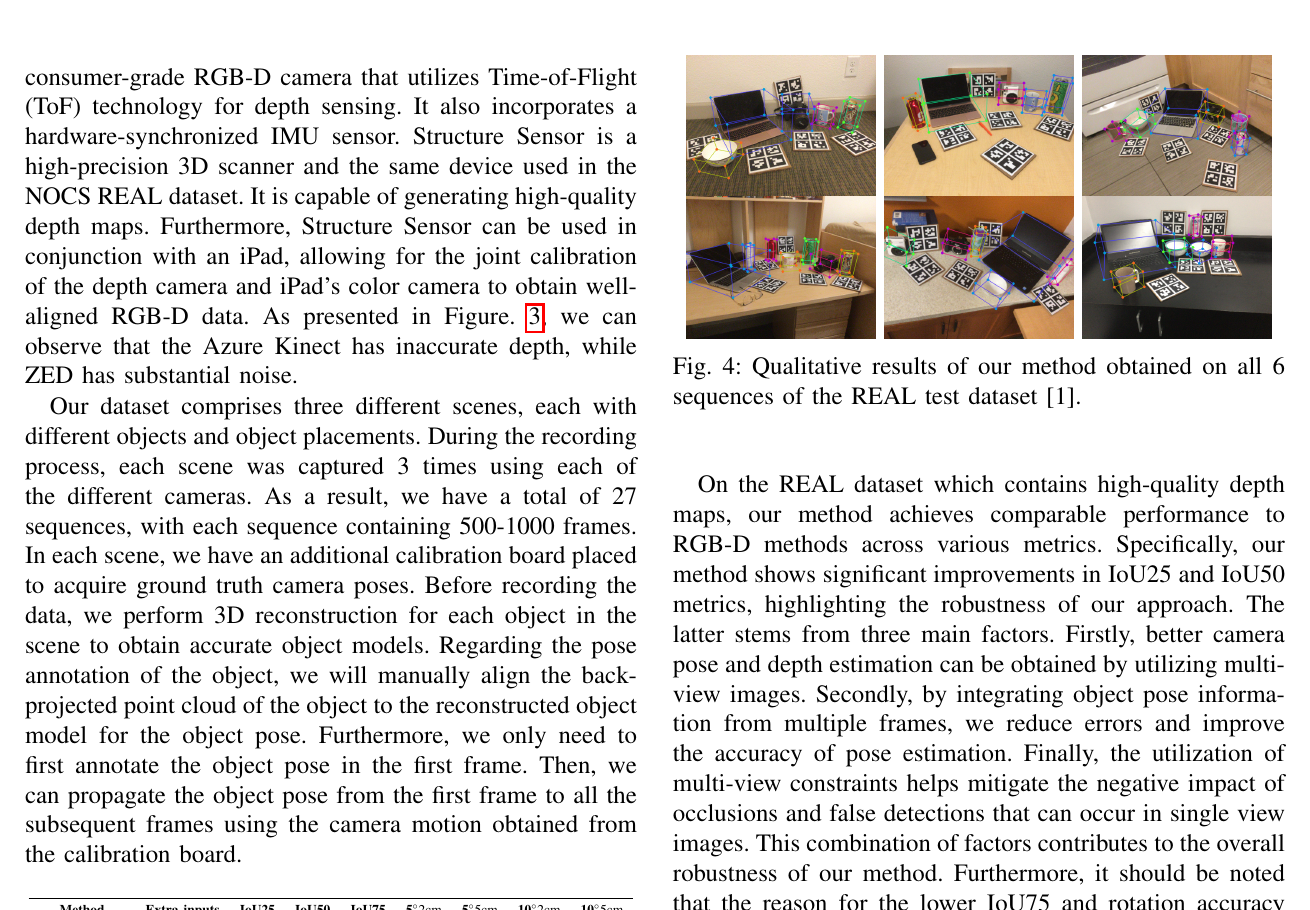
Original Figure 1: purple modules recover cameras and metric depth, orange estimates keyframe object poses, and green associates and optimizes across frames. Source: authors' public manuscript. Image copyright belongs to the authors and IEEE; reproduced here for academic analysis.Crop of an original results page: Figure 4 at upper right shows qualitative results for six REAL test sequences. The left describes MEREAL sensors, 27 sequences, and object annotation; a Table I header is visible at the bottom. Source: authors' public manuscript. Figure / table copyright belongs to the authors and IEEE; reproduced here for academic analysis.
Method and results at a glance
Optical flow and dense bundle adjustment recover keyframe camera poses and dense depth; scale may come from stereo baseline, IMU, or direct depth.
A single-frame module predicts instance masks and NOCS maps, aligned to dense depth through Umeyama-RANSAC for category-level pose and size.
IoU associates objects across frames; an object-level pose graph accumulates multi-view constraints against occlusion, false detections, and single-frame NOCS noise.
NOCS REAL 3D IoU25 / IoU50 mAP reaches 99.9 / 93.6, with 5°2cm 31.4.
MEREAL contains 27 sequences of 500–1000 frames each, captured with ZED, Azure Kinect, and Structure Sensor cameras.
Quick assessment
Strengths: explicit video and camera geometry rather than independent RGB-D frames; supports multiple scale sources.
Limits: stationary objects, reliable continuous SLAM, instance association, and scale information are required; within-category NOCS rotation remains a bottleneck.
Relevant topics: category-level video pose, object-level SLAM, and multi-view fusion.
Available src/paper-notes/mv-rope-iros2024/deep.md
In-depth paper notes
Support reproduction, comparison, related-work writing, and identifying opportunities for further research.
Paper Reading Notes (Deep): MV-ROPE
1. Key assessment
Moving cameras already provide continuous multi-view evidence, yet category-level pose methods often reduce it to independent RGB-D frames. MV-ROPE uses scale-aware dense SLAM for camera poses and metric depth, then fuses keyframe estimates in an object pose graph. Gains come from camera motion, stationary-object assumptions, and cross-frame identity constraints rather than a larger single-frame network.
2. System setting
Inputs are continuous RGB and scale information, supplied by stereo baseline, hardware-synchronized IMU, or direct depth. Outputs are camera trajectories, object 6D poses, and sizes in a global reference frame.
Key assumptions:
Objects remain stationary; the camera moves.
A segmentation network supplies classes and instance masks.
SLAM remains reliable under available texture and motion.
Scale readings are available to resolve monocular Sim(3) ambiguity.
It therefore cannot directly handle objects moved by people and is not single-frame RGB-only pose.
3. Three-module data flow
Original Figure 1. Single-frame NOCS poses are intermediate observations; final estimates come from keyframe and object-graph optimization. Source: authors' public manuscript. Image copyright belongs to the authors and IEEE; reproduced here for academic analysis.
3.1 Scale-aware dense monocular SLAM
A flow network predicts dense matches between neighboring keyframes, and dense bundle adjustment jointly optimizes camera poses and depth. Scale constraints in the objective remove arbitrary depth / translation scale. Multi-frame reprojection is smoother than single-frame consumer ToF depth and can recover structure in locally missing-depth regions.
3.2 Single-frame object estimation
Keyframes pass through instance segmentation and a lightweight NOCS predictor. For masked pixels:
NOCS supplies category canonical coordinates.
SLAM depth back-projects into camera coordinates.
Umeyama within RANSAC estimates a similarity transform.
Recover rotation, translation, and object scale.
Within-category shape, texture, and symmetry can still corrupt NOCS maps; multi-view processing reduces rather than eliminates these errors.
3.3 Object association and pose graph
Projected IoU associates objects between adjacent keyframes. Camera poses transform each object-pose observation into the global frame, and an object-level graph optimizes shared object states.
Cross-frame fusion provides:
Other viewpoints to support occluded frames.
Graph suppression of single-frame false detections / NOCS outliers.
Shared object sizes and poses across the sequence.
Outputs consistent with the SLAM world frame.
IoU-only association remains prone to identity switches among adjacent same-category objects, under rapid camera motion, or after long occlusions.
4. Experiments
Crop of an original results page: Figure 4 at upper right shows qualitative results for six REAL test sequences. The left describes MEREAL sensors, sequence acquisition, and object annotation; a Table I header is visible at the bottom. Source: authors' public manuscript. Figure / table copyright belongs to the authors and IEEE; reproduced here for academic analysis.
NOCS REAL:
Metric
MV-ROPE
IoU25
99.9
IoU50
93.6
IoU75
60.3
5°2cm
31.4
5°5cm
46.6
10°2cm
46.1
10°5cm
73.7
IoU25 / 50 is high, but strict rotation thresholds do not lead all RGB-D methods. The authors attribute limited NOCS rotation quality to within-category variation. Multi-view evidence mainly improves position, scale, and robustness; canonical-coordinate definitions remain unresolved.
MEREAL:
3 scenes, each recorded 3 times by each ZED, Azure Kinect, and Structure Sensor, totaling 27 sequences.
500–1000 frames per sequence.
A calibration board supplies camera-trajectory GT; manually registered 3D reconstructions and first-frame object poses propagate to later frames.
Mean rotation errors across sensors: 15.2° / 14.4° / 12.9°.
Mean translation errors: 8.3 / 3.6 / 6.6 cm.
Results show adaptability to scale sources and sensor differences, while substantial rotation errors remain.
5. Critical analysis
Strengths: models mobile-robot observation; interpretable SLAM depth and object graphs; custom sequences span three devices.
Limits: strong static-object assumption; IoU-only association; camera-trajectory failures systematically contaminate all objects; public REAL is adapted from single-frame data and does not fully establish video-protocol fairness.
Metric interpretation: IoU superiority does not imply strict rotation superiority; also inspect 5°2cm.
Extensions: appearance embeddings and uncertain association; joint camera / object optimization instead of a cascade; dynamic and articulated objects.
6. Reproduction checklist
Fix the scale-constraint source and noise model.
Report SLAM tracking failures and keyframe policy.
Save single-frame poses, pre- / post-optimization poses, and association IDs.
Use consistent NOCS symmetry definitions.
Measure camera, association, and object-pose errors separately.
Test dynamic objects that violate the static assumption.
7. Overall assessment
MV-ROPE advances category-level pose from single-frame perception to a multi-view geometric system. Video SLAM with scale constraints can replace unstable consumer depth, while NOCS rotation and object association remain limiting factors.